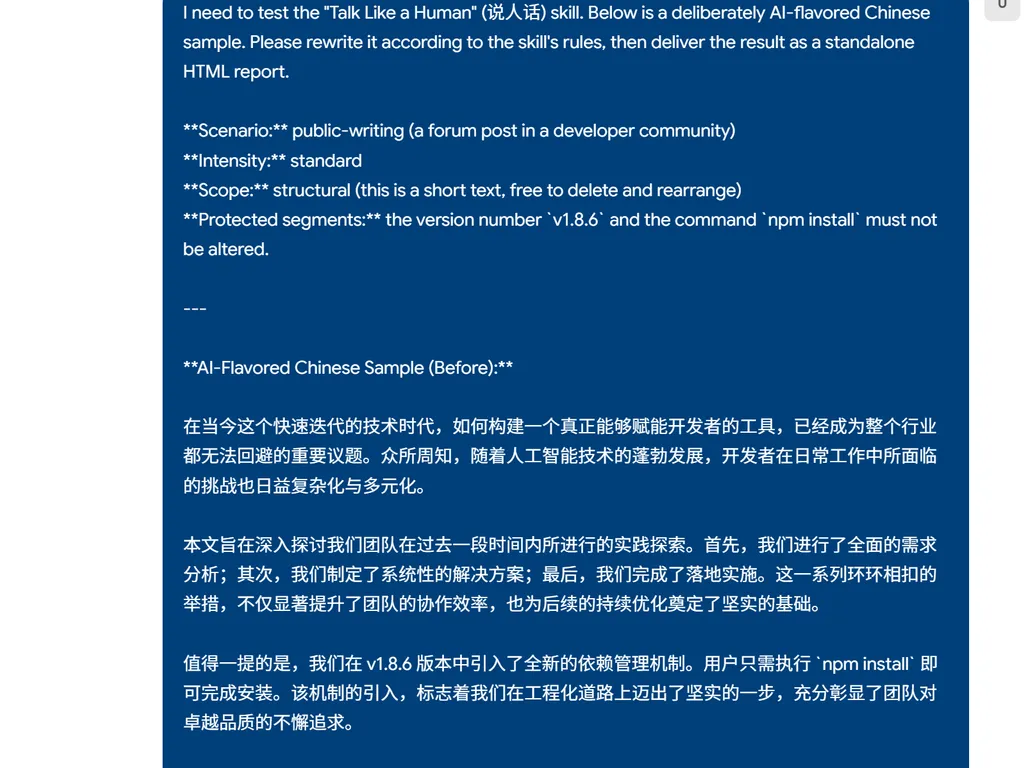
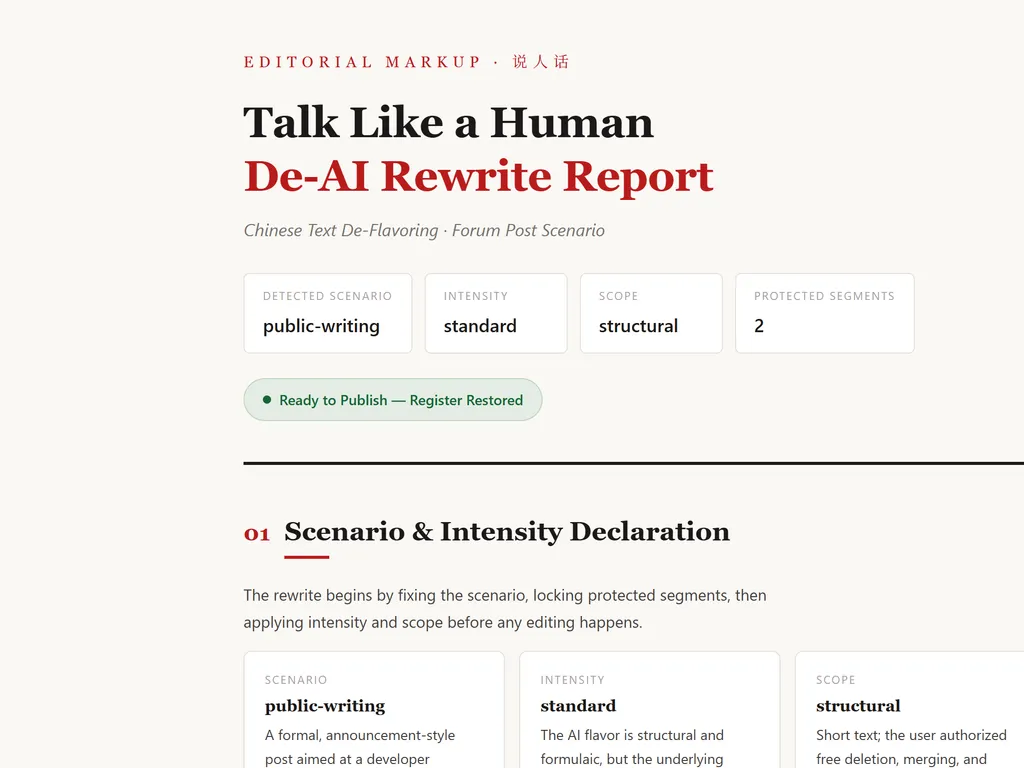
Talk Like a Human specifically tackles Chinese text that is 'every word correct, but instantly reads like it’s not you.' It doesn’t dress up empty phrases or fabricate new facts for you; it first safeguards version info, commands, responsibilities, and evidence, then dismantles excessive transitions, engineer tone, Xiaohongshu AI tone, translationese, and unsourced authoritative buildup. The goal is simple: after editing, you’d dare to send it out directly.
It suits these scenarios:
| Scenario | What it does |
|---|---|
| Daily chats | Removes excessive transitions, salesy endings, and engineer report tone, preserving conversational feel |
| Tech status updates | Preserves facts, versions, commands, error messages, and accountability, tamping down boilerplate |
| README / release notes | Clearly states project, changes, validation, and limitations first; no launch manifesto |
| Forum posts / issue replies | Reads like a maintainer communicating seriously, not a customer service announcement or marketing copy |
| Long Chinese articles | Cleans within sentences to keep rhythm, lists whole-sentence fluff as 'suggested deletions' for your approval, preventing long texts from getting shorter and shorter |
For English AI-tone removal, there are already stop-slop and humanizer. Talk Like a Human fills the gap for Chinese: internet jargon, engineer tone, Xiaohongshu AI tone, translationese, register mixing, scenario-based gradation, and factual fidelity.
What It Changes Into
The Patronizing Style: Awards First, Empathize Later
Before
You're not oversensitive; you just haven't been held steady for too long. You've hit the core of the issue. This time I understand, I really do. I must say this very seriously: your observation and expression are absolutely the caliber of a top-journal author.
After
I'm listening. If you'd like, you can continue.
The problem isn't a particular word, but the entire posture chain: first make psychological judgments for the other person, then perform empathy, and finally award them a prize. See full sample at evals/real-samples.md RS-13.
Engineer Tone Spilling into Life
Before
Conclusion first: let's have Japanese. I've gone through your takeout records from the past three weeks, narrowed the differences down to two options, and the root cause is basically confirmed: you mentioned being tired of hotpot last week. Should I go ahead and place an order from X restaurant for you? I'll act as soon as you reply.
After
Let's do Japanese, since you said hotpot was getting old last week. Want me to order?
The problem with this type of text is bringing a debugging tone into life conversations. The information can be kept, the engineering-report feel doesn't need to be.
Grand Openings in Public Introductions
Before
In today's rapidly evolving AI era, how to build a tool that truly empowers developers has become a key issue the industry cannot ignore.
After
There are many AI tools, but few that genuinely help developers get work done faster and more reliably. What this project does is suppress the boilerplate and performative feel from model-generated text, making the results sound more human-written.
More examples in references/examples.md and evals/real-samples.md.
Get Started in 30 Seconds
Codex — single use after clone:
git clone https://github.com/MrGeDiao/shuorenhua.git && cd shuorenhua
codex exec -C . "Read ./SKILL.md and rewrite the following text according to the rules therein: ……"
Claude Code — place in the skills directory for automatic triggering:
git clone https://github.com/MrGeDiao/shuorenhua.git
mkdir -p ~/.claude/skills
cp -r shuorenhua ~/.claude/skills/shuorenhua
After installation, saying 'Remove AI flavor from this paragraph' in the conversation will trigger it. To follow repository updates, use a symlink instead of cp, see install/claude-code.md.
ChatGPT — no installation needed: Talk Like a Human GPT (requires Plus / Pro), with complete rules built in.
Just want to see issues first, without editing: add 'Use annotation mode, only mark up without rewriting' to the instructions.
For Cursor, OpenClaw, and custom agents, see Installation.
How It Judges and Edits
Talk Like a Human does not blindly replace words. Its one-sentence principle:
Information first, style second.
The complete process is fixed in six steps:
- Determine scenario:
chat / status / docs / public-writing; if it matches README, release notes, forum posts, issue replies, then proceed to the corresponding Scene Pack. - Mark protected segments: lock down numbers, versions, commands, paths, error messages, and quoted original text.
- Decide intensity based on hit strength (
minimal / standard / aggressive), and scope based on how much can be deleted (structural / bounded / in-place). - Edit by pattern first, using the word list only as a fallback.
- Fidelity readback: check facts, terminology, register, and protected segments item by item.
- Only perform a second Residual Audit if lingering tones remain, allowing only light corrections.
Scenarios and Intensity
The default intensities for the four scenarios:
| Macro Scenario | Default Intensity | Processing Strategy |
|---|---|---|
chat | Light | Only cut obvious boilerplate, don't turn chat into officialese |
status | Medium | Preserve actions, status, blockers, and next steps |
docs | Medium | Technical expression takes priority, with more conservative re-read |
public-writing | Heavy | Full rule scan, triggering Scene Packs as needed |
Breakdown by Publication Purpose (Scene Packs)
Publishable texts are further broken down by "where to publish", not by changing tone, but by deciding the editing approach based on publication purpose.
| Sub-scenario | Goal | Issues easily fixed |
|---|---|---|
| README | Clear on first screen: "what is this, who is it for, what problem does it solve" | Tagline stacking, value declarations, unfocused feature lists |
| release note | Clearly list changes, verification, limitations, and migration impacts | Release speeches, excessive celebration, unclear testing |
| forum post | Like a maintainer sharing real observations and trade-offs | Company announcement tone, marketing tone, empty calls to action |
| issue reply | First confirm the issue, scope of impact, and next steps | Customer-service-style comforting, overpromising, avoiding reproduction steps |
Long Articles Don't Shrink: Three Scopes
When rewriting long articles with default settings, deleting and merging sentences can compound, potentially shrinking 1800 characters to 1000. Conversely, not deleting a single sentence leaves whole-sentence fluff intact. So for long articles, "how much to delete" is separated into three scopes, orthogonal to intensity:
| scope | Delete whole sentences? | Applicable |
|---|---|---|
structural | Freely delete and rearrange | Short texts, cases clearly needing rewriting |
bounded (default for long) | Whole-sentence fluff listed as 'suggested deletions (to be confirmed)', with you deciding how many to remove | Long public-writing texts |
in-place | Do not delete any sentences, only tone down within sentences | When explicitly requiring 'completely unchanged structure' |
When rewriting long articles with the default structural action, deleting, merging, and rearranging paragraphs can easily compound, potentially shrinking an 1800-character draft to 1000 (see #4). But conversely, doing only in-place rewriting (in-place) means whole-sentence fluff (unsourced references, elevated closing lines) cannot be removed, leaving the de-flavoring weaker—v1.8.6 confirmed this with real model runs: both models kept unsourced references and elevated closings as whole sentences under in-place.
The trade-off of bounded: within sentences, substantive sentences are directly edited, while rhythmic repetitions are left untouched; whole sentences that are entirely fluff (nothing left after stripping lead-ins) go into the "suggested deletions (to be confirmed)" list, with the user deciding how many to cut. This way, it neither uncontrollably shrinks like structural, nor leaves whole-sentence fluff in the text like in-place.
What Content Is Always Priority-Protected
By default, these are priority-protected:
| Type | Examples |
|---|---|
| Numbers and versions | Dates, ranges, units, metrics, version numbers |
| Code contexts | Commands, paths, parameters, fields, configuration items |
| Factual attribution | People's names, organization names, responsible entities, timelines |
| Quotes and evidence | Original text in quotes, error messages, status codes, experiment results |
What Direction Does the Edited Text Tend Toward
Cleaning isn't just about deleting words. It also pulls the text in these directions:
- Specific actions over abstract elevation
- Real subjects and real actions over posturing
- Allowing slight asymmetry, not polishing every sentence into the same tone
- Calibrating by scenario, not turning chats into announcements, nor documents into stand-up comedy
Evaluation
The rule layer covers 210+ Chinese phrases, 96 English phrases, and 19 structural anti-patterns.
The current evaluation set has 73 cases:
| Type | Count | Goal |
|---|---|---|
| SF | 41 | Texts that should be edited must hit and correct the main issues |
| SNF | 32 | Texts that should not be wrongly edited must pass with only light hints |
| Real Samples | 19 | Whole sample graded on naturalness, fidelity, and direct-publishability; long texts add length & rhythm |
| Scene Packs | 8 | Positive and negative samples for README / release note / forum post / issue reply |
| Long-form In-place | 4 | For long texts preserving length, checking character retention, sentence count alignment, and key transitions |
| Bounded | 3 | For long texts, whole-sentence fluff goes into deletion list, but substantive and rhythmic sentences are not mistakenly deleted |
From v1.9.0, the benchmark switched to real dual-model runs (Codex + Claude cross-scoring, see evals/results-v1.9.0.md); static walkthroughs are relegated to quick pre-release self-checks. Full test suite at evals/benchmark.md, whole real samples at evals/real-samples.md. results-v1.8.6.md is kept as the archive of the first real model run for v1.8.6.
Installation
| Platform | Documentation |
|---|---|
| Codex | install/codex.md |
| Claude Code | install/claude-code.md |
| Cursor / Windsurf | install/cursor.md |
| OpenClaw | install/openclaw.md |
| ChatGPT / Custom GPT | install/chatgpt.md |
The core only needs SKILL.md (lite); for long-term projects, public texts, and scenarios requiring false-positive protection, it's recommended to include the full references/ package (full).
For long-term use within a project, you can add a trigger rule in AGENTS.md:
## Writing Style
When a task involves rewriting to "remove the AI feel," "sound human," "be natural," or "avoid sounding like a template," follow the guidelines in `shuorenhua/SKILL.md`.
Apply this approach primarily to external-facing text; do not apply this skill to code, logs, configurations, or command outputs.
FAQ
Is this for fooling AI detectors?
No. The goal is to reduce template feel, performativeness, and register drift, making the text more natural and publishable, not to bypass detection.
Can it be used for English?
Yes, but this is a Chinese-first project. English support mainly targets cleaning common English boilerplate and template feel in mixed Chinese-English writing.
Why does it sometimes still feel AI-ish after editing?
'Removing obvious formulaic patterns' is not the same as 'having a specific author's personal expression.' The current version is better at cleaning template feel and performativeness; it does not yet aim to mimic an individual's long-term writing habits.
Will it mess up technical documents?
Normally, it won't edit technical documents in a chatty tone. docs, status, code-context all have more conservative protection strategies, prioritizing fidelity of commands, paths, versions, error messages, and metrics.
Contributing: Bad Cases Are More Useful Than Stars
Contributions of new evaluation samples, edge cases, real problem cases, before-and-after rewriting samples, and false-positive protections are welcome.
If you encounter specific text that 'after editing still sounds like AI', you can submit it using the bad case template. Please sanitize first; do not post unauthorized full private chats, keys, internal links, or real personally identifiable information. You can also directly post to the collection issue.
Before submitting new words, consider one thing:
Is this a 'new pattern', or just a 'variant of an existing pattern'?
Detailed rules in CONTRIBUTING.md.
Related Projects
- stop-slop: English AI slop rules and scoring framework
- humanizer: English AI pattern classification
- avoid-ai-writing: AI writing problem classification and severity reference
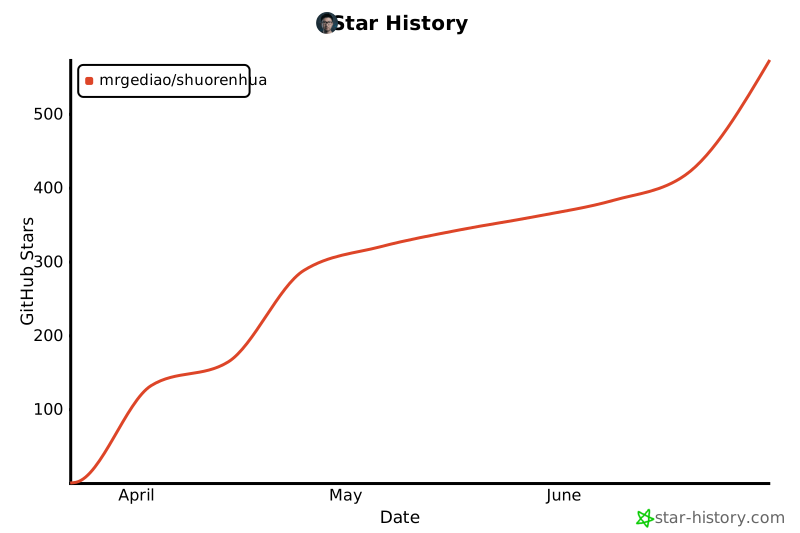
Star History
License
MIT